Computational Methods for Predicting Cellular Responses to Genetic & Chemical Perturbations
A comprehensive guide to state-of-the-art approaches combining single-cell transcriptomics,
CRISPR screens, and machine learning to predict how cells respond to perturbations.
Covering methods from 2016-2026, including recent critical evaluations of foundation models.
Tennis lens · perturbation modeling
发球出预测,回球见真章。
Perturbation modeling is a rally between model and lab — played across four very different courts. The model serves a prediction, the wet lab returns the measured response, and the gap between them is the loss, the benchmark, and the next drill. 四大满贯,四种场地,同一个问题:your prediction only counts if it holds on every surface.
Read the Rally.
「读懂发球,才接得住回球。」
Every perturbation experiment is a rally: the model serves a predicted response, the cell returns the measured one. And the tour never stays on one surface — hard court, clay, grass, and night sessions each change how the ball behaves, the way new cell types, platforms, and conditions change how a perturbation reads out. Six moments from the practice courts, re-read as the concepts this module's methods and benchmarks formalize.
Scene 1 · 发球权在你手上
You choose the serve
On the practice court you pick the serve — flat, slice, topspin — and the drill is only as informative as the serves you bother to practice.
Perturbation design. The intervention is the serve: gene knockout, drug, dose, combination. CRISPR screens are the cataloged serve drills — thousands of serves, one court. See the task ↓
Scene 2 · 出手前报落点
Call the landing spot
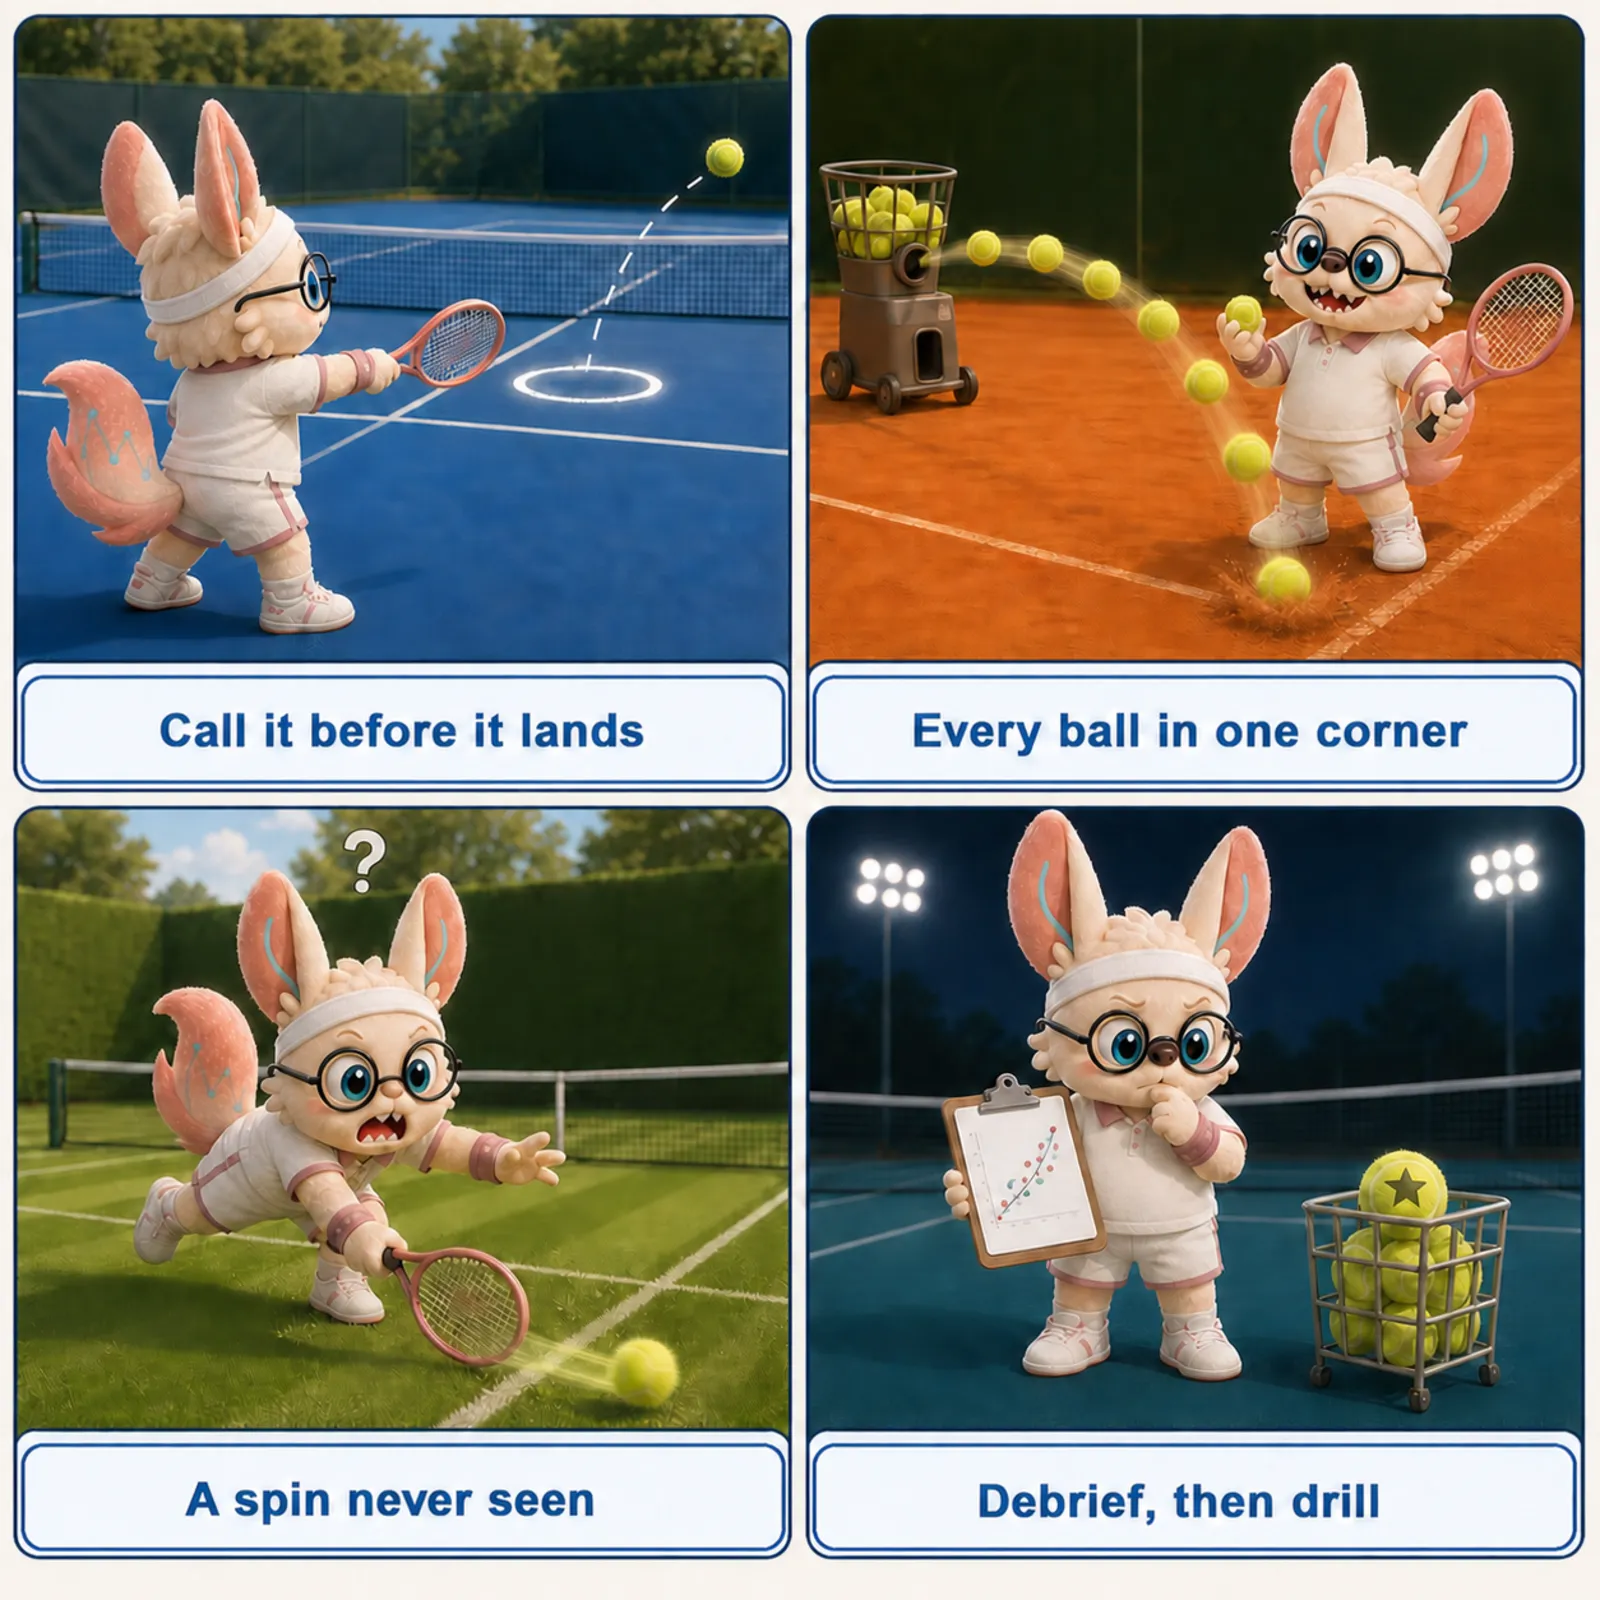
A rally player calls the return before the ball crosses the net — from the serve's spin, speed, and the opponent's stance, not from watching it land.
Response prediction. Given control state + serve, call the perturbed state: control + Δ = perturbed. The whole task is calling the Δ before the experiment returns it. See the formulation ↓
Scene 3 · 只会一招的对手
The one-play opponent
On clay at Roland Garros you meet the grinder: serves that look wild but all land in the same corner. Stand in that corner and you look like a genius predictor — until the tour moves to a different surface.
Systematic variation & the mean baseline. Any perturbation shifts the whole transcriptome in one direction, so predicting the perturbed-group mean scores like SOTA without learning anything per-gene. Always check what the corner-stander scores. See the critique ↓
Scene 4 · 没见过的旋转
The unseen spin
Drilling a hundred known serves on hard court is not the Championships. The first morning on grass, the ball skids through low and late — a serve you have never seen, and your read has to travel.
Unseen-perturbation generalization. The hard split is not random cells but new genes, new combinations, new doses. Most methods' scores drop sharply here; this is the split that counts. See benchmarks ↓
Scene 5 · 名将输给基本功
The star loses to fundamentals
A highlight-reel champion with no footwork loses to the club player who simply returns every ball deep. Reputation is not a return game.
Foundation models vs simple baselines. On standard perturbation benchmarks, large pretrained models often fail to beat train-mean or linear baselines. Scale is not mechanism; check the fundamentals first. See the evidence ↓
Scene 6 · 赛后复盘
The match debrief
Good players debrief every rally — which reads were wrong, by how much, on which serve — and choose tomorrow's drill from the errors, not from the highlight reel.
Honest metrics + active learning. Debrief with centroid-referenced metrics (top-DEG Δ, E-distance), then spend the next experiment where the error is largest: optimal intervention design closes the loop. See the loop ↓
One player, four courts. Call it before it lands (hard-court prediction) · every ball in one corner (the clay grinder = the mean baseline) · a spin never seen (first time on grass = an unseen perturbation) · debrief, then drill (honest metrics under the lights).
每一杆都是实验,每个回合都在校准 — every serve is a prediction, every return a measurement; the rally is the loop.
19Curated Papers & Resources
5Method Categories
8Datasets & Benchmarks
2016-2026Years Covered
🎯 Core Concepts
The Challenge
Understanding how cells respond to perturbations (genetic knockouts, drug treatments, etc.) is
fundamental to biology and medicine. However:
Experimental Limitations: Testing all possible perturbations is prohibitively
expensive and time-consuming
Combinatorial Explosion: For n genes, there are n(n-1)/2 possible pairwise
combinations - grows exponentially
Cellular Heterogeneity: Individual cells respond differently to the same
perturbation
Context-Dependence: Effects vary across cell types, conditions, and genetic
backgrounds
Data Quality: Single-cell data is sparse, noisy, and affected by batch effects
Key Biological Facts
Only ~41% of gene perturbations have measurable transcriptome-wide effects
(Replogle et al., 2022)
Most effects are small: 86.6% below 0.01 log-fold change
Network structure matters: 77.3% of direct regulators (distance 1 in GRN)
confer moderate-to-strong effects
The Opportunity
Computational prediction methods aim to:
Predict cellular responses to unseen perturbations without experiments
Model combinatorial perturbations (e.g., gene pairs) trained only on
single perturbations
Enable rational experimental design by prioritizing promising perturbations
Uncover mechanisms of action and genetic interactions
Accelerate drug discovery by predicting compound effects
📊 Method Categories
1. Variational Autoencoder (VAE) Approaches
scGen - Latent Space Arithmetic
2019Nature MethodsVAE
Pioneering VAE-based approach using vector arithmetic in latent space for perturbation
prediction. Assumes homogeneous responses and additive perturbation effects.
First to use VAEs for perturbation prediction
Simple latent arithmetic: perturbed = control + perturbation_vector
Struggles with cell-type-specific and heterogeneous responses
Combines compositionality, disentanglement, and interpretability through sparse global
perturbation variables. Each perturbation targets sparse subset of latent dimensions.
Conditional VAE with additive composition of perturbation and covariate embeddings.
Predicts counterfactual distributions but requires training data for each perturbation.
Uses Input Convex Neural Networks (ICNNs) to learn transport maps between unpaired control
and perturbed cell distributions. Predicts single-cell-level responses.
ICNNs ensure convexity of transport maps for guaranteed optimality
Handles unpaired data - doesn't need matched control/treated cells
Predicts individual cell trajectories, not just population means
Generalizes to holdout patients and cross-species transfer
scGPT - Generative Pretrained Transformer for scRNA-seq
2024Nature MethodsTransformer
Foundation model pretrained on 33+ million cells. Uses masked gene modeling with binned
expression values. Fine-tuned for perturbation prediction with adapter layers.
100M+ parameters, generative pre-training on massive scale
Gene-specific embeddings + expression value binning
State: Predicting Cellular Responses Across Diverse Contexts
2025bioRxiv (June 2025)Transformer
Set-based transformer trained on 100M+ perturbation cells across 70 cell lines and
167M observational cells. Arc Institute's first virtual cell model using bidirectional
attention over cell populations.
State Embedding (SE) + State Transition (ST) architecture
50%+ improvement in perturbation effect discrimination on Tahoe-100M
2× accuracy in identifying true differentially expressed genes
NOTE: Released June 2025 - too recent for independent validation
Tabular-attention foundation model trained on 149M cells that performs true in-context
learning at the cell-set level, reframing perturbation prediction as prompting rather
than fine-tuning: give the model a labelled prompt cell-set at inference time and it
predicts the response to a new, unseen perturbation with no weight updates.
Ranks 1st in 28/31 in-context-learning evaluations, spanning zero-shot perturbation, donor, and condition transfer
Both State and STACK are 2026-era transformer approaches, but they represent opposite
adaptation paradigms: State fine-tunes a set-based transformer on the target task, while STACK
uses in-context learning with no weight updates. For the pretraining objectives, tokenisation
choices, and scaling laws behind these and other foundation models, see the
Pretraining & Foundation Models module.
5. GRN-Based & Physics-Inspired Methods
CellOracle - GRN-Based Perturbation Prediction
2023NatureGRN
Two-stage pipeline: (1) infer base GRN from scATAC-seq, (2) refine with scRNA-seq
using Bayesian/Bagging Ridge regression. Linear propagation through GRN.
Integrates chromatin accessibility (scATAC-seq) for regulatory links
Physics-inspired approach using linear response theory: Δx = Σu where Σ is covariance
matrix from control cell fluctuations. Bayesian inference with Horseshoe priors.
Covariance matrix Σ_ij = ⟨δx_i δx_j⟩ from control cells
R² up to 1.0 on synthetic networks with known ground truth
CellOracle and CIPHER predict perturbation responses through a fixed or
inferred regulatory graph. For methods that instead discover the underlying
causal graph from perturbation data (DCDI, ENCO, and related structure-learning approaches), see
the Causal Inference module
— the two problems share data (Perturb-seq screens) but answer different questions: this module
asks "what will happen," causal inference asks "what regulates what."
📈 Large-Scale Datasets & Platforms (2024-2025)
Industrial-scale perturbation atlases provide massive training data for foundation models.
These represent significant experimental advances in scale and throughput.
Largest public perturbation atlas: 100M cells, 50 cancer cell lines, 1,100 drugs.
Vevo Therapeutics' Mosaic platform with Parse GigaLab sequencing. Open-sourced on
Arc Virtual Cell Atlas and HuggingFace.
SNP-based genetic demultiplexing (>98% accuracy)
1,786 sublibraries, 1.4 trillion reads
Context-dependent drug response across diverse cancer backgrounds
scPerturb: Harmonized Single-Cell Perturbation Data
2024Nature MethodsRepository
Harmonized repository of 44 datasets from 25 publications: 32 CRISPR + 9 drug + 3 datasets
from other perturbation/readout modalities, average 160K cells per dataset. Introduces
Energy statistics for perturbation quantification.
Standardized processing across diverse experimental platforms
E-statistics framework for perturbation effect quantification
X-Atlas/Orion: Genome-Wide Perturb-seq via FiCS Platform
2025bioRxivPlatform (8M cells)
Fix-Cryopreserve-ScRNAseq platform achieving 8M cells targeting all human protein-coding genes.
sgRNA abundance as dose-dependent proxy (R=0.91 with KD efficiency).
Ahlmann-Eltze, Huber & Anders: Deep-learning-based gene perturbation effect prediction does not yet outperform simple linear baselines
2025Nature MethodsBenchmark
Systematic benchmark pitting five foundation models plus two additional deep-learning
methods against deliberately simple linear/additive baselines for single- and
double-gene-perturbation transcriptome prediction. None of the deep models beat the
baselines.
Linear additive model often has LOWER MSE than foundation models
Detected mode collapse: predictions don't vary across perturbations
For double perturbations, additive baseline outperformed all deep learning
Changed how field evaluates perturbation prediction methods
Arc Institute's recurring benchmark competition for perturbation prediction, aiming to
establish rigorous, CASP-style standards for the field. The inaugural 2025 challenge
(H1 hESC context generalization) closed with results in early 2026; the 2026 edition
raises the bar to zero-shot CRISPRi-response prediction across six held-out cell lines
with no released training set.
2025 winner: Team BM_xTVC (BioMap Research) with xTrimoSCPerturb, combining deep learning with classical statistical features — 5,000+ participants across 114 countries, 1,200+ teams, 300+ final submissions
Even the winning approach needed hand-engineered statistical features layered on deep learning — pure end-to-end learning has not yet solved the problem
2026 edition: $100K grand prize (NVIDIA, 10x Genomics, Ultima Genomics); harder zero-shot generalization task, no released training data
Adopts PerturBench's rank-based metrics as part of the evaluation standard
PerturBench: Benchmarking Machine Learning Models for Cellular Perturbation Analysis
2024NeurIPS / Nat Methods 2025Benchmark Framework
Standardized benchmarking framework from Altos Labs — unified data loaders, biologically
meaningful train/test splits, a modular model zoo, and rank-based metrics designed to
complement (and expose the limits of) standard RMSE/R² fit measures.
Rank-based metrics later adopted as part of the Virtual Cell Challenge's evaluation standard
Shows simpler architectures often match complex ones and surfaces mode-collapse failure modes across published models
Modular model zoo + diverse datasets at multiple scales enable apples-to-apples comparison across methods
Replogle et al. 2022 (Cell): Largest to date - K562 Genome-Wide (>2.5M cells,
9,867 genes targeted with CRISPRi), K562 Essential (~400K cells), RPE1 Essential (~300K cells).
Only 41% of perturbations show measurable effects.
Norman et al. 2019 (Science): K562, 287 perturbations (100 single + 131 double
combinations), CRISPRa, 19,264 genes measured. Primary benchmark for combinatorial perturbations.
Srivatsan et al. 2020 sci-Plex (Science): Chemical perturbations, 188 compounds
× 4 doses, K562/A549/MCF-7 cell lines, ~650K cells total.
scPerturb (Peidli et al., Nature Methods 2024): Harmonized repository of 44
datasets from 25 publications — 32 CRISPR + 9 drug + 3 other-modality datasets — average
160K cells per dataset.
Standard Evaluation Metrics
Population-Level (Fit-Based):
MSE/RMSE on top 1,000-2,000 most expressed genes
Pearson Correlation (PCC) between predicted and observed profiles
Pearson Delta (R²): cor(ŷ - y^control, y - y^control)
R² Score: Standard regression explained variance
Distribution-Based:
Energy Distance: 2·E[||X-Y||] - E[||X-X'||] - E[||Y-Y'||]
Wasserstein Distance (W2): Optimal transport cost
MMD (Maximum Mean Discrepancy): With RBF kernel
Rank-Based (Critical for Mode Collapse Detection):
Rank metric: Measures how well predictions rank-order cells
Transposed-Rank: More challenging variant
Matrix Distance: Similarity matrix divergence
These metrics are ESSENTIAL - many papers only report MSE/R² which miss mode collapse
🔄 Emerging Trends & Future Directions
2016-2018: Foundation Era
Perturb-seq (Dixit 2016, Adamson 2016) establishes experimental paradigm for pooled
perturbation screens with single-cell readouts. CROP-seq (Datlinger 2017) provides
alternative guide capture method. ~200K cells per study.
2019-2022: First Computational Methods
scGen (2019) pioneers VAE approach. Norman et al. (2019) provide key combinatorial
perturbation dataset. Replogle et al. (2022) scale to genome-wide with >2.5M cells.
CellOracle (2023) leverages GRNs.
2023: Diverse Methodological Advances
Neural OT (CellOT) and VAEs (SAMS-VAE, CPA) provide alternative frameworks. Each method
claims superiority on different metrics and datasets.
2024: Foundation Models & GNNs Reach Journal Publication
GEARS (dual knowledge-graph GNN) reaches Nature Biotechnology. scFoundation and scGPT
are adapted for perturbation tasks.
2025: Consolidation & New Directions
100M+ cell datasets emerging — Tahoe-100M, X-Atlas/Orion, and Mixscale all
released. Physics-inspired methods (CIPHER) and biological
priors (scLAMBDA with LLM embeddings, code) show up. Field recognizes need for
proper baselines and evaluation.
2026: Scaling, In-Context Learning, and the First Challenge Results
The Virtual Cell Challenge's inaugural 2025 competition wraps up — the first CASP-style
blind evaluation for perturbation prediction — and reveals that even the winning approach
needed hand-engineered statistical features layered on deep learning; the harder,
zero-shot 2026 edition launches immediately after. STACK (bioRxiv) reframes perturbation
prediction as in-context learning: no fine-tuning, just a labelled prompt cell-set at
inference time. Geneformer-scaling (Nat Comput Sci) brings 4-bit QLoRA quantization to
genome-scale virtual knockout screens, cutting a 316M-parameter screen from $25k/33 days
to <$5k/6 days. The field converges on rank-based metrics and mandatory linear
baselines following the Ahlmann-Eltze benchmark.
🚀 Key Research Frontiers
Understanding Why Deep Models Underperform: Fundamental question - why do
foundation models with 100M+ parameters often fail to beat linear regression?
Proper Evaluation Standards: Field needs to adopt rank-based metrics and
mandatory baseline comparisons
Temporal Dynamics: Most methods focus on static endpoints; trajectory-aware
models needed for perturbation kinetics
Combinatorial Perturbations: Scaling from single-gene to multi-target
perturbations remains challenging
Multi-Modal Integration: Combining transcriptomics, proteomics, imaging,
and spatial data in unified frameworks
Mechanistic Interpretability: Moving beyond correlation to causal
understanding of perturbation effects
Primary Tissues: Most validation on cell lines; primary cells and
in vivo models underexplored
📚 Method Comparison
Method
Year
Architecture
Scale
Key Innovation
Perturb-Seq
2016
Experimental
~10K-200K cells
CRISPR + scRNA-seq pooled screens
scGen
2019
VAE
~50K cells
Latent space vector arithmetic
CellOT
2023
Neural OT
~50K cells
ICNN transport maps, single-cell predictions
SAMS-VAE
2023
VAE
~120K cells
Sparse additive mechanism shifts
CPA
2023
VAE
~100K cells
Compositional perturbation + covariates
GEARS
2024
GNN
~600K cells
Dual knowledge graphs (GO + coexpression)
CellOracle
2023
GRN
~100K cells
scATAC-seq informed GRN inference
scGPT
2024
Transformer (100M)
33M cells pretrain
Generative pretraining (BUT often underperforms)
scFoundation
2024
Transformer (100M)
50M cells
Read-depth-aware (BUT mode collapse issues)
CIPHER
2025
Statistical Physics
~1.4M cells
Linear response theory (Δx = Σu)
State
2025
Transformer (Set-based)
100M+ cells pretrain
State Embedding + State Transition, bidirectional attention over cell populations
STACK
2026
Transformer (ICL)
149M cells pretrain
True in-context learning — no fine-tuning, no weight updates
Note: Publication years reflect official journal publication dates.
Some papers (e.g., GEARS) appeared online earlier than print publication.
💡 Practical Implementation Guide
Choosing the Right Method
Decision Framework
Step 1: Always implement simple baselines first:
Additive model: Δ_combo = Δ_gene1 + Δ_gene2
Linear regression with gene features
Mean prediction (no-change model)
For Drug Response Prediction:
Chemical perturbations → CellOT (single-cell), CPA if have dose info
Cross-cell-type generalization → Test on multiple cell lines
Dose-response modeling → Methods that model continuous covariates
For Genetic Perturbations:
Single-gene → GEARS (if genes in GO), CIPHER, or simple linear models
Combinatorial → Test additive baseline first, then GEARS or SAMS-VAE
Avoid black-box transformers if interpretability is priority
For Zero-Shot / Few-Shot Transfer (no fine-tuning):
STACK's in-context-learning recipe → provide a labelled prompt cell-set at inference time, no weight updates. Strongest for cross-tissue and cross-perturbation transfer, but requires a model pretrained on cell-set-level inputs in the first place — not a free downstream choice for arbitrary architectures.
Zero-shot in-silico knockout via a pretrained scFM's attention/embedding perturbation (e.g., Geneformer) → cheaper than full fine-tuning if you only need a coarse ranked target list.
If adaptation is still needed → Geneformer-scaling's 4-bit QLoRA recipe fits a full 316M-parameter fine-tune on a single consumer GPU, making genome-scale in-silico screens routinely affordable (<$5k vs $25k for a 30K-cell × 4K-gene screen).
Common Pitfalls & Best Practices
Data Quality: Ensure high UMI counts (>1000), proper doublet removal,
batch correction before modeling. Use established pipelines (Scanpy, Seurat).
Evaluation: Use held-out PERTURBATIONS, not held-out cells from
training perturbations. This tests generalization properly.
Baseline Comparisons: Always compare against simple linear models.
Mode Collapse Detection: Use rank metrics, visualize prediction distributions.
If all predictions look similar, model has collapsed.
Generalization: Test cross-dataset, cross-cell-type, and out-of-distribution
generalization. Don't just report in-distribution performance.
Reproducibility: Report all hyperparameters, random seeds, preprocessing steps,
and provide code. Use version control.
Biological Validation: Computational predictions should be validated with
targeted experiments on key predictions.
Software Ecosystem
Scanpy: Standard preprocessing, analysis, visualization (Python)
scvi-tools: Implementations of scVI, scGen, CellOT
Causal Inference — the discovery counterpart to this module's prediction: "what regulates what" (DAG/GRN structure) vs. "what will happen" (perturbation response). CellOracle and CIPHER predict through a graph; the causal-inference module recovers that graph in the first place.
Pretraining & Foundation Models — the training paradigms (masked pretraining, in-context learning, scaling laws) behind State, STACK, scGPT, and scFoundation.
🛠️ Hands-On Practice
The walkthrough below runs a complete, purely computational perturbation-prediction experiment end to end: load a Perturb-seq dataset (Norman 2019 CRISPRa or Adamson 2016 CRISPRi), split it so that entire perturbations — not cells — are held out, train GEARS on the seen perturbations, predict post-perturbation expression for the unseen ones, and score the predictions with MSE on the top differentially expressed genes plus Pearson delta against a control-mean baseline. Everything is retrospective: no new experiments, only re-analysis of published screens.
Environment & packages
GEARS pins an older PyTorch Geometric stack, so give it its own environment rather than sharing one with scGPT or scvi-tools. Install PyTorch (matching your CUDA version) first, then the PyG companion wheels, then GEARS. scGen and CPA live in the scvi-tools ecosystem and can share a second environment; pertpy provides the dataset loaders and the differential-expression utilities used for scoring.
# conda / mamba recommended
conda create -n pertpred python=3.10 -y
conda activate pertpred

# 1. PyTorch first — pin the exact version so it matches the PyG wheel below
pip install torch==2.1.0 --index-url https://download.pytorch.org/whl/cu121

# 2. PyTorch Geometric + companion wheels (GEARS' graph backend).
#    The wheel URL is locked to torch 2.1.0+cu121 — if you install a
#    different torch/CUDA combo above, update this URL to match
#    (see https://data.pyg.org/whl/ for the available combinations).
pip install torch_geometric
pip install torch_scatter torch_sparse \
    -f https://data.pyg.org/whl/torch-2.1.0+cu121.html

# 3. Core stack
pip install cell-gears scanpy anndata pertpy

# Separate env for the VAE/latent-arithmetic family (scvi-tools pins conflict)
# conda create -n pertvae python=3.10 -y && conda activate pertvae
# pip install scgen cpa-tools scvi-tools scanpy
Hardware. Norman 2019 (~110k cells, 287 perturbations) trains on a single 16 GB GPU in roughly 1–2 hours for 20 epochs; CPU-only training is possible but an order of magnitude slower. Peak host RAM is dominated by the dense gene × perturbation tensors GEARS builds — budget 32–64 GB. Genome-scale Replogle K562 (>2.5M cells) needs a compute node with 128 GB+ RAM and is usually subsampled before any exploratory run.
Data structures & formats
AnnData — adata.X holds normalized, log1p-transformed expression (GEARS expects log-space, not raw counts); adata.obs carries the perturbation label; adata.var must contain a gene_name column so perturbation identifiers can be matched to measured genes.
Perturbation label convention — GEARS parses adata.obs["condition"] as "GENE+ctrl" for singles, "GENEA+GENEB" for doubles, and the literal string "ctrl" for unperturbed cells. Malformed labels are the single most common load failure.
Gene co-expression / GO knowledge graph — two graphs are auto-built by PertData: a gene–gene co-expression graph over the measured transcriptome, and a perturbation–perturbation similarity graph derived from Gene Ontology term overlap. The GO graph is what lets GEARS place a never-seen perturbed gene near functionally related seen genes and thus emit a non-trivial prediction for it.
Split dictionary — pert_data.set2conditions maps train/val/test to lists of condition strings. This is the object to inspect (and to save alongside results) when you want the split to be reproducible.
DE gene index — adata.uns["rank_genes_groups_cov_all"] stores, per condition, the ranked list of differentially expressed genes versus control. All headline metrics are computed on the top 20 of these, not on the full transcriptome.
Model outputs — model.predict([["GENE"], ["GENEA", "GENEB"]]) returns a dict keyed by condition, each value a length-n_genes vector of predicted mean post-perturbation expression in log space.
Minimal code walkthrough
Load Norman 2019 through the GEARS dataloader, create a split that holds out entire unseen perturbations, train, predict, and evaluate. The evaluation block is the part worth reading closely: it computes MSE on the top-20 DE genes, Pearson delta, and the control-mean baseline in the same loop so the three numbers are always reported together.
import numpy as np
from scipy.stats import pearsonr
from gears import PertData, GEARS

# 1. Load a published Perturb-seq screen. "norman" = Norman et al. 2019
#    (K562, CRISPRa, 100 singles + 131 doubles); "adamson" = Adamson et al.
#    2016 (K562, CRISPRi, single-gene only). PertData downloads the h5ad,
#    normalizes/log1p's it, and builds the gene co-expression graph.
pert_data = PertData("./data")
pert_data.load(data_name="norman")

# 2. Hold out entire PERTURBATIONS, not cells. Held-out cells from a
#    perturbation the model already trained on measure nothing but denoising.
#    split="simulation" mimics the realistic case: some test perturbations
#    involve genes never perturbed during training (unseen singles), and some
#    doubles combine a seen gene with an unseen one (0/1/2-seen subgroups).
pert_data.prepare_split(split="simulation", seed=1, train_gene_set_size=0.75)
pert_data.get_dataloader(batch_size=32, test_batch_size=128)

print({k: len(v) for k, v in pert_data.set2conditions.items()})

# 3. Train. GEARS embeds each perturbed gene via the GO-derived perturbation
#    graph, so an unseen gene inherits signal from its functional neighbours
#    instead of falling back to the training mean.
model = GEARS(pert_data, device="cuda")
model.model_initialize(hidden_size=64)
model.train(epochs=20, lr=1e-3)
model.save_model("gears_norman")

# 4. Predict post-perturbation expression for held-out conditions.
#    Singles are single-element lists; doubles are two-element lists.
test_conds = pert_data.set2conditions["test"]
preds = model.predict([c.replace("+ctrl", "").split("+")
                       for c in test_conds if c != "ctrl"])

# 5. Reference quantities from the raw AnnData
adata = pert_data.adata
ctrl_mean = np.asarray(
    adata[adata.obs["condition"] == "ctrl"].X.mean(axis=0)
).ravel()
gene_names = adata.var["gene_name"].values
de_map = adata.uns["rank_genes_groups_cov_all"]   # condition -> ranked DE genes

# 6. Evaluate. Three numbers, always together:
#      (a) MSE on the top-20 DE genes  — all genes dilutes the signal to noise
#      (b) Pearson delta               — cor(pred - ctrl, true - ctrl)
#      (c) the control-mean baseline   — "predict no change at all"
rows = []
for cond in test_conds:
    if cond == "ctrl" or cond not in preds:
        continue
    true_mean = np.asarray(
        adata[adata.obs["condition"] == cond].X.mean(axis=0)
    ).ravel()
    pred_mean = preds[cond]

    de20 = de_map[cond][:20]
    idx = np.where(np.isin(gene_names, de20))[0]

    mse_de   = np.mean((pred_mean[idx] - true_mean[idx]) ** 2)
    mse_base = np.mean((ctrl_mean[idx]  - true_mean[idx]) ** 2)

    # Pearson DELTA, not raw Pearson. Raw cor(pred, true) over all genes runs
    # ~0.98 for essentially any model, because most genes do not respond to
    # the perturbation and both vectors are dominated by the shared baseline
    # expression profile. Subtracting the control mean removes that shared
    # component and scores only what the model actually had to get right:
    # the direction and magnitude of the CHANGE.
    r_delta = pearsonr(pred_mean[idx] - ctrl_mean[idx],
                       true_mean[idx] - ctrl_mean[idx])[0]
    r_raw   = pearsonr(pred_mean[idx], true_mean[idx])[0]

    rows.append((cond, mse_de, mse_base, r_delta, r_raw))

mse_de, mse_base, r_delta, r_raw = (np.nanmean([r[i] for r in rows])
                                    for i in (1, 2, 3, 4))
print(f"MSE (top-20 DE)          : {mse_de:.4f}")
print(f"MSE control-mean baseline: {mse_base:.4f}   <- must beat this")
print(f"Pearson delta            : {r_delta:.3f}")
print(f"Pearson raw (inflated)   : {r_raw:.3f}")

# 7. Break the score out by generalization difficulty. A model can look strong
#    overall while being useless on the only split that matters.
subgroups = pert_data.subgroup["test_subgroup"]   # e.g. unseen_single, combo_seen0/1/2
for grp, conds in subgroups.items():
    sub = [r for r in rows if r[0] in set(conds)]
    if sub:
        print(f"{grp:15s} n={len(sub):3d}  "
              f"Pearson delta={np.nanmean([r[3] for r in sub]):.3f}")
Common pitfalls & tips
Score DE genes, not all genes. Averaging MSE over ~19,000 measured genes buries the few dozen that actually respond; the metric then mostly rewards reproducing the baseline transcriptome. Restrict headline MSE and correlation to the top 20–100 DE genes per condition, and state the gene set explicitly — results are not comparable across papers that use different ones.
Report the control-mean baseline or the number means nothing. "Predict the unperturbed mean for every condition" is a deceptively strong baseline: on Replogle only about 41% of perturbations produce a measurable effect, so no-change is exactly right most of the time. Several published models fail to beat it on unseen perturbations. Always print baseline MSE next to model MSE.
Pearson delta, never raw Pearson. Raw cor(predicted, observed) sits near 0.98 for almost any model because both vectors are dominated by shared baseline expression. Only cor(pred − ctrl, true − ctrl) scores the change itself, and it typically drops to 0.3–0.6 — that gap is the honest measure of what the model learned.
Unseen-single and unseen-double splits are different problems. Predicting a double knockout where both genes were seen individually is largely an additivity test that a simple ΔA + ΔB model handles well. Predicting a perturbation of a gene never seen in training requires genuine transfer through the GO/co-expression graph and is far harder. Report the subgroups separately (combo_seen0/1/2, unseen_single); a pooled average hides the failure mode.
Weak knockdown looks identical to model failure. CRISPRi efficiency varies substantially per guide, and a target that was only partially repressed produces a near-null expression profile. The model is then penalized for predicting a real effect that the experiment never induced. Filter test perturbations to those with a verified on-target knockdown (or a significant Energy-distance/E-test effect versus control) before scoring, and report how many conditions were dropped.
Batch and cell-line confounding travels with the screen. Norman/Adamson/Replogle are K562-dominated and each has its own 10x chemistry, depth, and gRNA library. A model trained on one and evaluated on another is measuring batch transfer as much as perturbation biology; check that predicted deltas are not simply reproducing the donor/lane axis, and integrate or regress out batch before cross-dataset claims.
MOI determines how noisy your labels are. Low-MOI screens give near-clean one-guide-per-cell assignment; high-MOI designs boost combinatorial coverage but leave ambiguous or multiply-assigned cells. Run Mixscape (pertpy) to drop cells with no detectable perturbation signature, and treat guide-assignment confidence as a filter, not as ground truth.
Keep the split file, not just the seed.prepare_split behavior can change across GEARS versions; save pert_data.set2conditions to disk with the results so the same held-out perturbations can be re-scored later by a different method.